Article · Latent Space ·

How Anthropic ships Claude with Claude: Separating the Brain from the Hands

Latent Space

In a Latent Space episode, Anthropic's heads of engineering (Katelyn Lesse) and product (Angela Jiang) discuss the launch of Claude Opus 5.5, which has held the top-ranked LLM title for about a month, and the engineering behind the Claude Platform. The episode covers how Opus 5.5 is cheaper to run than its predecessor, changes to API integration including preserving thinking blocks across turns to protect reasoning against distillation, and how early access programs run evaluations in customers' own harnesses to see the model on tasks Anthropic's own products do not cover. A central mental model is separating an agent's 'brain' (session log and harness) from its 'hands' (the sandbox that executes code), which improves latency and reliability and adds security by keeping credentials out of the sandbox. The episode also covers Managed Agents' memory feature ('dreaming'), a roadmap that has shifted more attention toward safety, and the practice of evaluating agents.

Read at latent.space Summary written by an AI model from the original. Check the original before you rely on a detail.

Tools in this story

Each tool opens in the Heidelberg AI Curriculum: what it does, what it costs, how to start.
Related stories

All stories

ArticleThe Decoder

Open-weight model GLM 5.3 built full Firefox exploit chains with zero human input in under 48 hours

Researchers at Epoch AI report that the open-weight Chinese model GLM 5.3 autonomously built full Firefox exploit chains with no human input, exploiting the 'patch gap' between when security fixes appear in code and when they reach users. The model identified disguised security fixes, chained vulnerabilities with a previously unpublished flaw to bypass browser sandbox protections, and could read local files when a user visited a webpage. Attacks cost about $1,000 in API fees per Firefox version across six versions released Sept 17–Oct 26, taking 12 hours for the fastest and up to 48 hours. No API providers tested triggered safety guardrails. Mozilla patched the flaw in Firefox 159.0 (Oct 27). The same setup spent roughly $100,000 on Google Chrome without producing an equivalent exploit. Researchers warn the patch-gap risk spans the software industry and note untested benchmark data suggesting Kimi K3.1 Pro could outperform GLM 5.3 on offensive cyber tasks.

ArticleLatent Space

[AINews] Building AIE CODE: The top Coding Agent Conference

AINews covers three AI developments: Mistral Large 4 ('Le Chonk') shipped as an open-weights release built for agentic coding and cybersecurity, with 1.05T total and 52B active parameters, 1M context, text+image input, and pricing near $0.70/$2.10 per 1M input/output tokens; OpenAI now monitors all frontier RL runs, evaluations, and internal Codex use using activation probes, reviewer models over reasoning and tool use, and investigator agents; and Anthropic says Claude now produces a preliminary misuse assessment immediately after each response, which it says has surfaced misuse its classifiers were not designed to catch.

VideoNate Herk

I Told Claude to "Make it better" 100 Times (It Went Too Far)

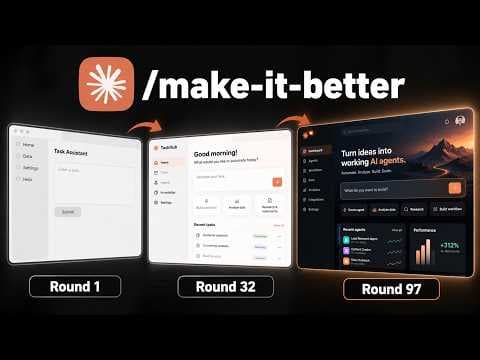
In a YouTube video, creator Nate Herk tested Claude Code by giving it a deliberately ugly coffee shop website and instructing it to 'make it better' 100 times in a row, running the experiment twice—once with Claude Sonnet 5.5 and once with Claude Opus 5.5, both at medium effort. Each run was in a clean room (new session, no skills, plugins, or memory), so each model relied only on its own knowledge and built-in tools. With Sonnet, the model made small, careful changes across 100 rounds, generating 11 images and 2 videos at a cost of about $29.93 in API billing, with code lines growing linearly while the actual quality gains were unclear. Milestones included the first AI-generated image and mobile-ready site (round 1), the first scroll animation (round 24), and the first online-ordering form (round 32). With Opus, the model kept adding features until the site reached 21,000 lines and started breaking itself. Neither model used web search even though it could. Herk's takeaway is that AI is not naturally good at thinking outside the box, and setting vague goals leads to getting stuck around the 80th improvement, so prompting must be specific and actively drive innovation to push past the 90-100 mark.

ArticleThe Decoder

Paris-based Mistral releases "Le Chonk," a strong coding model that still trails China overall

Mistral has released the weights for Mistral Large 4, nicknamed "Le Chonk," a model of about one trillion parameters (52 billion active) trained entirely in Europe and distributed under a modified MIT license that allows running it on own hardware. Independent testing by Artificial Analysis rates it 26 points on its Intelligence Index, behind open Chinese models such as DeepSeek V4.1 Flash and GLM-5.3 (32 points) and far behind the leading systems from Anthropic and Google. Mistral says it leads open models on coding, and independent benchmarks show it is fast (161 tokens per second) and cheap, but it trails Claude Opus 5.5 on coding indexes and ranks third among open models on cyber defense. Mistral cut the API price from $1.36/$4.18 to $0.70/$2.10 per million input/output tokens, and the model is available on Microsoft Foundry.