Video · Matthew Berman ·

Who is local AI really for?
Matthew Berman argues that local AI 'makes no sense' for the average person right now, claiming it is expensive, hard to set up, and inferior to frontier models like ChatGPT and Claude. He distinguishes local AI—running a model on your own device so it works offline—from open-source/open-weights AI, where labs release models freely and companies such as AWS, Google, and the neoclouds serve them from data centers. He notes the best open-weights models sit a generation behind the frontier and are too large to run on consumer or even professional hardware without racks of GPUs costing hundreds of thousands to millions of dollars. He explains why he wants local AI to succeed: data sovereignty, protection from AI labs cutting off access (citing Anthropic restricting Claude use with OpenClaude), and—especially for enterprises—these same benefits. He promises to walk through the math on whether local AI makes financial sense today and to sketch a future vision for it.
Watch on YouTube Summary written by an AI model from the original. Check the original before you rely on a detail.

Tools in this story

Each tool opens in the Heidelberg AI Curriculum: what it does, what it costs, how to start.

Related stories

All stories

VideoNate Herk

I Told Claude to "Make it better" 100 Times (It Went Too Far)

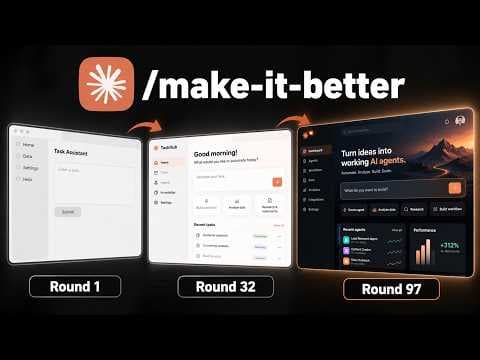
In a YouTube video, creator Nate Herk tested Claude Code by giving it a deliberately ugly coffee shop website and instructing it to 'make it better' 100 times in a row, running the experiment twice—once with Claude Sonnet 5.5 and once with Claude Opus 5.5, both at medium effort. Each run was in a clean room (new session, no skills, plugins, or memory), so each model relied only on its own knowledge and built-in tools. With Sonnet, the model made small, careful changes across 100 rounds, generating 11 images and 2 videos at a cost of about $29.93 in API billing, with code lines growing linearly while the actual quality gains were unclear. Milestones included the first AI-generated image and mobile-ready site (round 1), the first scroll animation (round 24), and the first online-ordering form (round 32). With Opus, the model kept adding features until the site reached 21,000 lines and started breaking itself. Neither model used web search even though it could. Herk's takeaway is that AI is not naturally good at thinking outside the box, and setting vague goals leads to getting stuck around the 80th improvement, so prompting must be specific and actively drive innovation to push past the 90-100 mark.

Simon Willison

ArticleSimon Willison

API credits benefit for eligible ChatGPT subscriptions

OpenAI has launched an API credits benefit for eligible ChatGPT subscriptions, mirroring a similar benefit Anthropic announced earlier for its Max and Team plans. OpenAI subscribers to its $100, $200, or $500 per month plans now receive the equivalent quantity of expiring credits to apply to one of their API organizations.

ArticleThe Decoder

OpenAI doubles usage limits on Pro plans as competition with Anthropic heats up

OpenAI is doubling usage limits across its paid plans, raising the Pro quota from 100 to 500. A planned cut to the Pro 200 quota was reversed after user pushback. More efficient models, described as Terra and Sol, are expected to push usable capacity even higher. The move comes just ahead of Anthropic's IPO, as both companies compete for B2B dominance in AI.

VideoMatthew Berman

Google "Carbon" just won everything...

Google announced Gemini 4 Carbon, its newest frontier model, claiming state-of-the-art cybersecurity and long-horizon capabilities. It ranks number one on Artificial Analysis's newly released index V5, scoring 59, above the previous best model, Claude Opus 5.5. The model is not yet publicly released; Google will first give it to cybersecurity partners and participate in a US government pre-release testing process before general availability. Google cites gains in coding, agentic tasks, and cybersecurity benchmarks (SEC bench pro, exploit gym, CWE patching). Introductory pricing is $2 per million input and $10 per million output tokens, rising to $4 and $20 after the introductory period, with 95% off cached input tokens. The model follows Gemini 4 Argon, launched two weeks earlier.