Harbor + Docker Sandboxes: Run Safe, Reproducible Agent Evals
Docker's Harbor can now run every eval task in Docker Sandboxes, which are MicroVM environments for running agents like Claude Code, Codex, and Cursor safely. With Sandboxes you can define custom network policies for fair, reproducible evals, and you can run evals locally or in the cloud, starting free on Docker Sandboxes on local surfaces and scaling up.
Read at docker.com Summary written by an AI model from the original. Check the original before you rely on a detail.
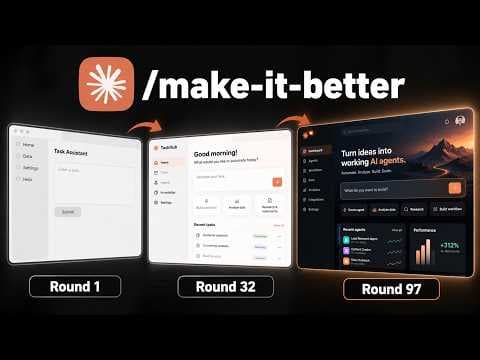
In a YouTube video, creator Nate Herk tested Claude Code by giving it a deliberately ugly coffee shop website and instructing it to 'make it better' 100 times in a row, running the experiment twice—once with Claude Sonnet 5.5 and once with Claude Opus 5.5, both at medium effort. Each run was in a clean room (new session, no skills, plugins, or memory), so each model relied only on its own knowledge and built-in tools. With Sonnet, the model made small, careful changes across 100 rounds, generating 11 images and 2 videos at a cost of about $29.93 in API billing, with code lines growing linearly while the actual quality gains were unclear. Milestones included the first AI-generated image and mobile-ready site (round 1), the first scroll animation (round 24), and the first online-ordering form (round 32). With Opus, the model kept adding features until the site reached 21,000 lines and started breaking itself. Neither model used web search even though it could. Herk's takeaway is that AI is not naturally good at thinking outside the box, and setting vague goals leads to getting stuck around the 80th improvement, so prompting must be specific and actively drive innovation to push past the 90-100 mark.
An official Docker video describes a case in which an AI code review agent invented a CVE that did not exist and recommended dangerous fixes. It explains how Docker Sandboxes contain agents and why their output needs verification.
Google announced Gemini 4 Carbon, its newest frontier model, claiming state-of-the-art cybersecurity and long-horizon capabilities. It ranks number one on Artificial Analysis's newly released index V5, scoring 59, above the previous best model, Claude Opus 5.5. The model is not yet publicly released; Google will first give it to cybersecurity partners and participate in a US government pre-release testing process before general availability. Google cites gains in coding, agentic tasks, and cybersecurity benchmarks (SEC bench pro, exploit gym, CWE patching). Introductory pricing is $2 per million input and $10 per million output tokens, rising to $4 and $20 after the introductory period, with 95% off cached input tokens. The model follows Gemini 4 Argon, launched two weeks earlier.
In a 'show me your workflow' episode, Matt Wolfe interviews builder Nate Herk about three AI workflows he uses daily. First, an automated short-form video editing workflow built with Claude Code that Herk says can produce around 20 reels in a single morning, handling ideation, scripting, B-roll selection, and AI-generated video. Second, an AI expert panel called The Roast Room used to make better decisions. Third, an AI social media manager that researches, creates, and publishes Instagram content. Herk explains his approach to building 'skills' by reverse-engineering proven work and using a 'golden dataset' (like model evals) to guide output, noting AI still lags behind humans in music and sound design.